Try the demo
Explore MAPLES with sample materials and see how assessment and feedback fit together.
Try the Demo
Access is by invitation. Choose “Request access” on the sign-in page.
Our purpose
Our mission is to raise the quality and expand the possibilities of medical education by empowering educators, researchers, and students with accessible, responsible AI tools for teaching, learning, assessment, and discovery.
Keep educators and learners at the center, with people guiding decisions and interpreting feedback.
Make methods, evidence, and limitations clear so results can be questioned, evaluated, and improved.
Respect the people behind the data and plan access, use, and storage around institutional needs.
Meet people where they work, with adaptable tools and approachable paths to exploration and adoption.
Take the next step
Start with the demo, explore local OASIS setup, or talk with our team.
Explore MAPLES with sample materials and see how assessment and feedback fit together.
Access is by invitation. Choose “Request access” on the sign-in page.
Explore the OASIS project and plan a setup for your own teaching or research environment.
Bring your goals and questions. Let's explore what MAPLES and OASIS could look like at your institution.
Technical setup, local workflows, and research collaboration.
This project — "Scaling and Validating AI-Enabled Simulation Assessment Across University of Texas Medical Schools" — is an 18-month, $300,000 initiative funded by the UT REAL Health AI Pilot Program, which supports collaborative, implementation-focused AI initiatives across UT Health-Related Institutions.
The UTSW production workflow moves from OSCE capture to AI grading and faculty review, turning recorded clinical encounters into actionable feedback for students.
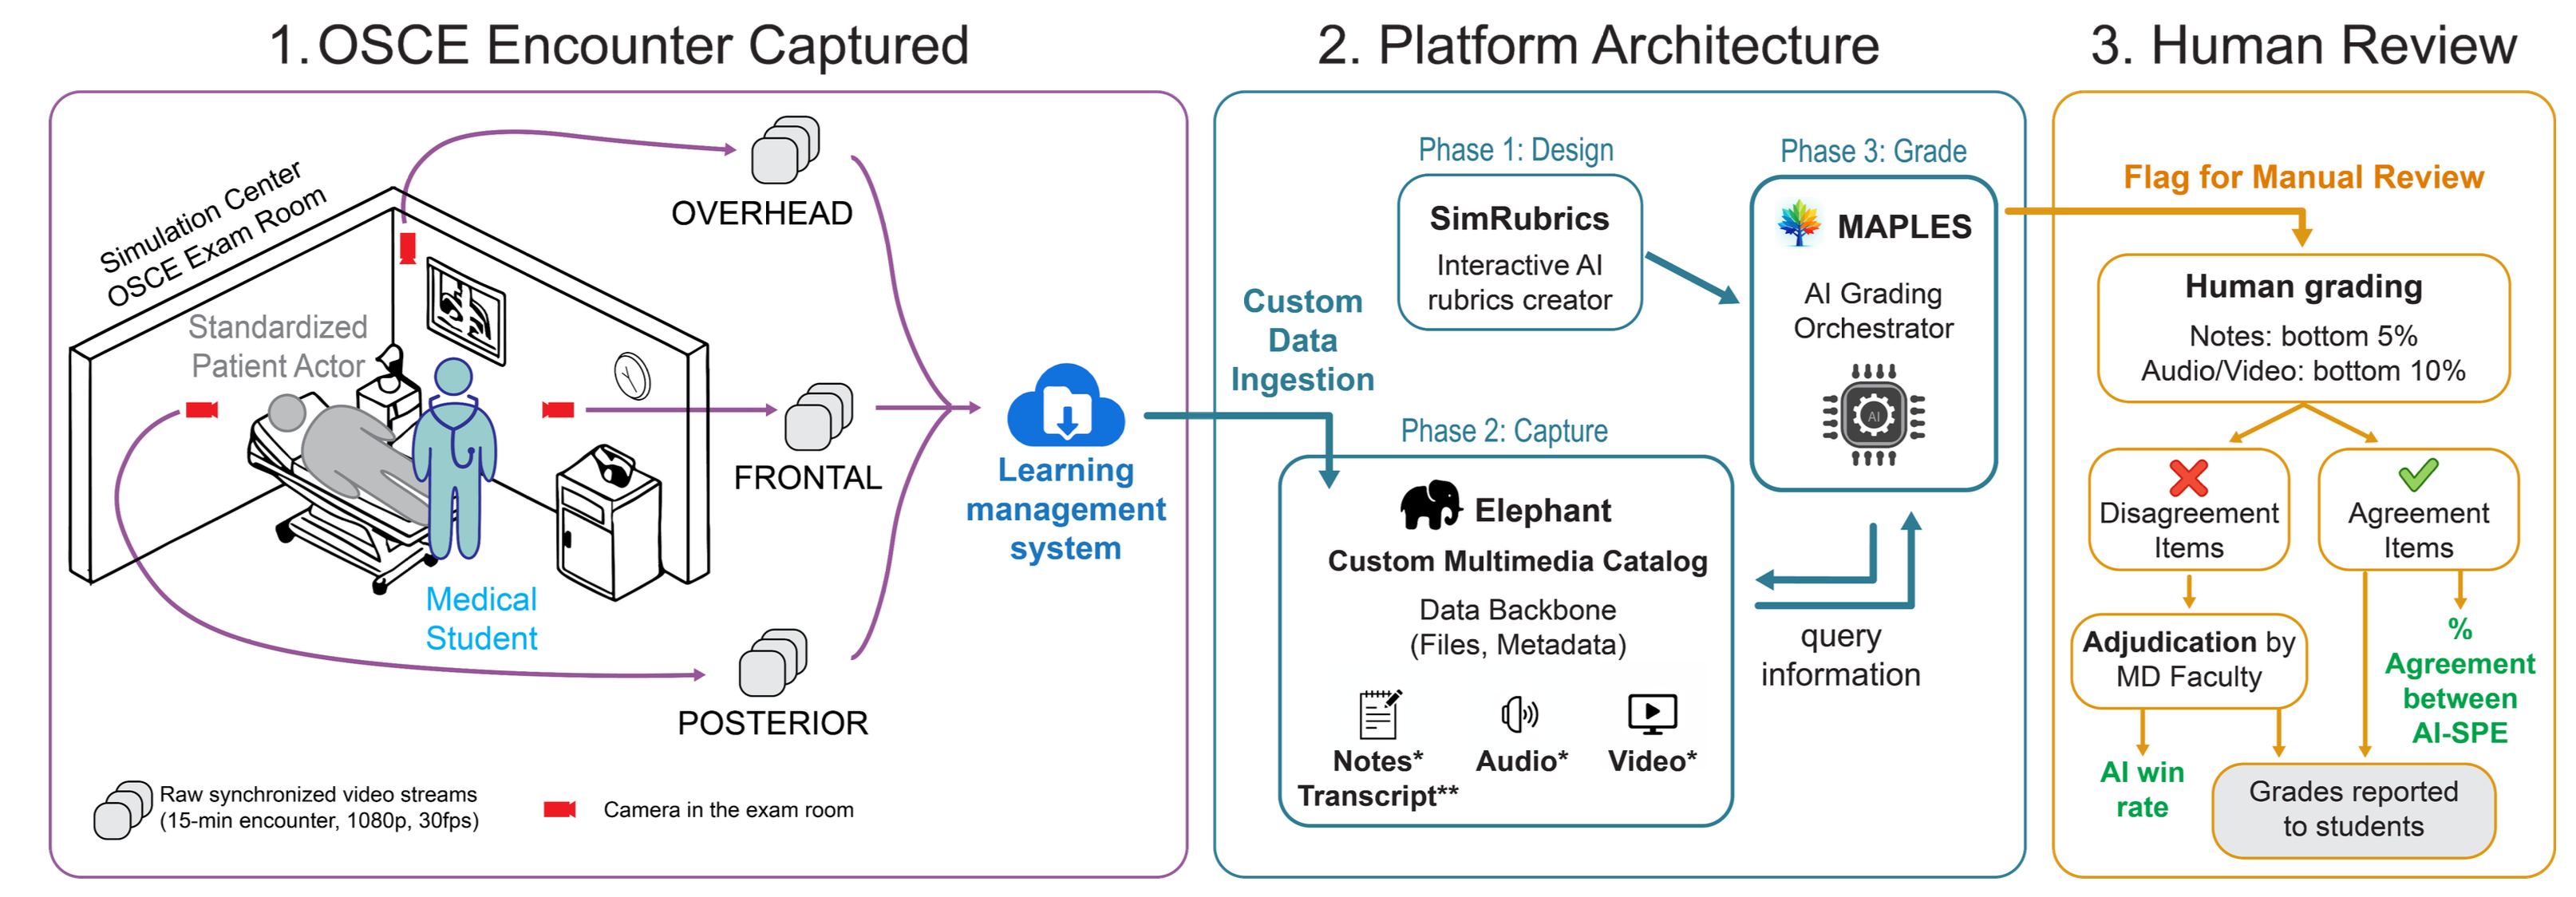
In the UTSW production workflow, 1. Capture — multi-angle video from the simulation center flows into a learning management system; 2. Platform — SimRubrics authors AI-compatible rubrics, Elephant catalogs the multimedia data, and MAPLES orchestrates AI grading; and 3. Review — faculty review flagged items, adjudicate disagreements, and grades are reported to students with full provenance.
Partner schools travel these stops at their own pace. This is a process map, not a live scoreboard.
1
Getting ready
Champion · local plan
2Partner schools now
Approvals
IRB · agreement · tech path
3
Retrospective check
AI vs human on past cases
4
Live use
Prospective grading
An Objective Structured Clinical Examination (OSCE) is how medical schools assess whether students can demonstrate clinical skills in a standardized medical scenario.
Students are assessed on communication, history taking, physical examination, clinical reasoning, and medical knowledge. They rotate through rooms, each with a standardized patient presenting a different scenario. Many programs record encounters and use detailed rubrics to support structured clinical competency assessment.
The result is an enormous volume of encounters that need expert review. That's where AI comes in.
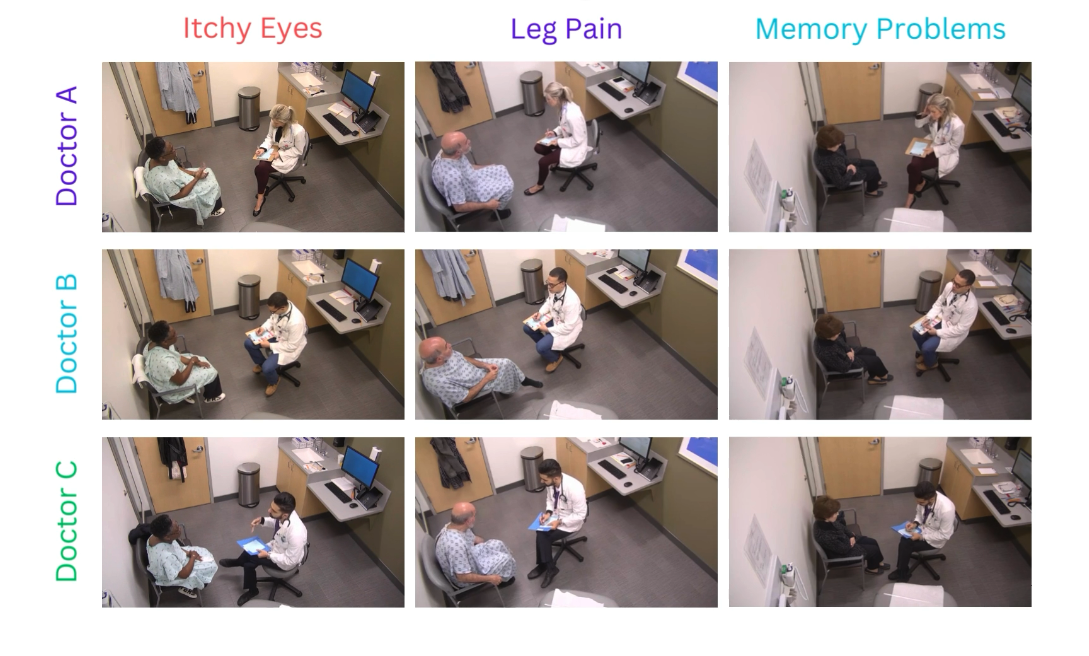
A UTSW OSCE workflow with medical students rotating through stations, encounters recorded from overhead cameras, and performance evaluated with clinical rubrics.
The educators who train tomorrow's doctors deserve better tools.
Large OSCE administrations can require many hours of faculty and standardized-patient educator review. That workload can delay feedback that is most useful when delivered promptly.
In a 300-encounter retrospective medRxiv preprint, standard human evaluators achieved quadratic weighted kappa = 0.732 against a physician-adjudicated reference. Consistent rubric interpretation and review remain important parts of reliable assessment.
Assessment tools, rubrics, and infrastructure are commonly managed within each school. That makes it harder to compare practices, share validated tools, and adopt what works at peer institutions.
Our Approach
AI that helps educators give students faster, more consistent, and more detailed feedback on their clinical skills.
A 300-encounter retrospective medRxiv preprint reported three-camera MAPLES agreement of quadratic weighted kappa = 0.830 against a physician-adjudicated reference, compared with 0.732 for standard human evaluators against the same reference. Faculty retain final authority and review cases routed for human judgment.
More than 7,000 encounters have been graded in UTSW production. The grant proposal estimates that the six participating medical schools collectively represent more than 3,200 medical students.
UT-HIP is one infrastructure option under technical feasibility review alongside UTSW-managed and site-specific paths. Final hosting, governance, and access controls have not been selected and remain subject to site-specific approvals.
Beyond text-based note grading: the platform supports audio, transcript, and video analysis for physical examination identification and clinical reasoning assessment.
AI-compatible rubric design that each school can customize to their own educational philosophy — shared tools and best practices, not one-size-fits-all templates.
Multi-site IRB routing, data-use agreements, and human-in-the-loop review practices are being developed with partner sites. A reusable public playbook is a project deliverable. It is not published on this site yet.
UTSW production and the six-school consortium.
How our principles guide assessment, evaluation, and deployment.
AI augments, not replaces, expert judgment. In the UTSW production workflow, prespecified low-scoring cases are routed for mandatory human review, and faculty retain final authority over grades.
Sites activate at their own pace along two axes: modality (text → transcript → video) and study design (retrospective → prospective). No site is forced into lockstep.
Every AI grading decision is logged with full provenance. Rubric versions, model parameters, and confidence scores are captured for audit and research.
The project is required to disseminate this capability, not only to operate it at one site. A participating school can run the workflow locally through OASIS, with the UTSW team helping stand that up. The public OASIS page describes the stack; local stand-up is arranged with the team, not by installing a public release.
This project is one of several initiatives funded by the UT REAL Health AI Pilot Program ($300,000, awarded March 2026, 18 months). Infrastructure planning is being coordinated with UT Southwestern Information Resources and Enterprise Data Services, while the UT Health Intelligence Platform remains a prospective UT System path subject to hosting, governance, and site approvals. The project originated at the UTSW Simulation Center, built by the Jamieson Lab.